

Free 365 Days Exam Updates NSE7_SOC_AR-7.6 dumps with test Engine Practice
Updated Verified NSE7_SOC_AR-7.6 dumps Q&As - 100% Pass Guaranteed
Fortinet NSE7_SOC_AR-7.6 Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 41
Using the default data ingestion wizard in FortiSOAR, place the incident handling workflow from FortiSIEM to FortiSOAR in the correct sequence. Select each workflow component in the left column, hold and drag it to a blank position in the column on the right. Place the four correct workflow components in order, placing the first step in the first position at the top of the column.
Answer:
Explanation:
Explanation:
Step 1: FortiSIEM event log
Step 2: FortiSIEM incident
Step 3: FortiSOAR alert
Step 4: FortiSOAR incident
Exact Extract: "FortiSIEM: Event: An event refers to a single log or data point collected from a monitored device. It's the most basic unit of information received by FortiSIEM, such as a firewall log or a system alert." The guide also states: "Incident: An incident in FortiSIEM is created when a correlation rule is triggered." Exact Extract: "This slide explains how to map fields between FortiSIEM incidents and FortiSOAR alerts during the ingestion process. Use the wizard to define how FortiSIEM data populates FortiSOAR alert fields." Exact Extract: "FortiSOAR ingests FortiSIEM incidents as alerts... If the alert is not a valid threat, then the analyst can close it as a false positive. Otherwise, the analyst can open an incident." The correct sequence is FortiSIEM event log # FortiSIEM incident # FortiSOAR alert # FortiSOAR incident . FortiSIEM first receives raw event logs from monitored devices. If those events match a correlation rule, FortiSIEM creates a FortiSIEM incident . The FortiSOAR default data ingestion wizard then ingests FortiSIEM incidents into FortiSOAR as alerts , not as FortiSOAR incidents directly. After triage and validation, the analyst or playbook can escalate the alert into a FortiSOAR incident .
Technical Deep Dive: FortiSIEM and FortiSOAR use different object models. FortiSIEM "incident" means a correlation result from event analytics. FortiSOAR "alert" is the first SOAR-side record created from that SIEM incident. FortiSOAR "incident" is a higher-level case-management container used after validation. This separation is intentional: not every SIEM incident deserves full incident- response handling. FortiGate NP/CP offloading is irrelevant because this workflow is log ingestion and case orchestration, not firewall packet acceleration.
NEW QUESTION # 42
Refer to Exhibit:
A SOC analyst is creating the Malicious File Detected playbook to run when FortiAnalyzer generates a malicious file event. The playbook must also update the incident with the malicious file event data.
What must the next task in this playbook be?
- A. A local connector with the action Update Incident
- B. A local connector with the action Update Asset and Identity
- C. A local connector with the action Run Report
- D. A local connector with the action Attach Data to Incident
Answer: A
Explanation:
* Understanding the Playbook and its Components:
* The exhibit shows a playbook in which an event trigger starts actions upon detecting a malicious file.
* The initial tasks in the playbook include CREATE_INCIDENT and GET_EVENTS.
* Analysis of Current Tasks:
* EVENT_TRIGGER STARTER: This initiates the playbook when a specified event (malicious file detection) occurs.
* CREATE_INCIDENT: This task likely creates a new incident in the incident management system for tracking and response.
* GET_EVENTS: This task retrieves the event details related to the detected malicious file.
* Objective of the Next Task:
* The next logical step after creating an incident and retrieving event details is to update the incident with the event data, ensuring all relevant information is attached to the incident record.
* This helps SOC analysts by consolidating all pertinent details within the incident record, facilitating efficient tracking and response.
* Evaluating the Options:
* Option A:Update Asset and Identity is not directly relevant to attaching event data to the incident.
* Option B:Attach Data to Incident sounds plausible but typically, updating an incident involves more comprehensive changes including status updates, adding comments, and other data modifications.
* Option C:Run Report is irrelevant in this context as the goal is to update the incident with event data.
* Option D:Update Incident is the most suitable action for incorporating event data into the existing incident record.
* Conclusion:
* The next task in the playbook should be to update the incident with the event data to ensure the incident reflects all necessary information for further investigation and response.
References:
Fortinet Documentation on Playbook Creation and Incident Management.
Best Practices for Automating Incident Response in SOC Operations.
NEW QUESTION # 43
Your company is doing a security audit To pass the audit, you must take an inventory of all software and applications running on all Windows devices Which FortiAnalyzer connector must you use?
- A. FortiCASB
- B. FortiClient EMS
- C. ServiceNow
- D. Local Host
Answer: B
Explanation:
* Requirement Analysis :
* The objective is to inventory all software and applications running on all Windows devices within the organization.
* This inventory must be comprehensive and accurate to pass the security audit.
* Key Components :
* FortiClient EMS (Endpoint Management Server) :
* FortiClient EMS provides centralized management of endpoint security, including software and application inventory on Windows devices.
* It allows administrators to monitor, manage, and report on all endpoints protected by FortiClient.
* Connector Options :
* FortiClient EMS :
* Best suited for managing and reporting on endpoint software and applications.
* Provides detailed inventory reports for all managed endpoints.
* Selected as it directly addresses the requirement of taking inventory of software and applications on Windows devices.
* ServiceNow :
* Primarily a service management platform.
* While it can be used for asset management, it is not specifically tailored for endpoint software inventory.
* Not selected as it does not provide direct endpoint inventory management.
* FortiCASB :
* Focuses on cloud access security and monitoring SaaS applications.
* Not applicable for managing or inventorying endpoint software.
* Not selected as it is not related to endpoint software inventory.
* Local Host :
* Refers to handling events and logs within FortiAnalyzer itself.
* Not specific enough for detailed endpoint software inventory.
* Not selected as it does not provide the required endpoint inventory capabilities.
* Implementation Steps :
* Step 1 : Ensure all Windows devices are managed by FortiClient and connected to FortiClient EMS.
* Step 2 : Use FortiClient EMS to collect and report on the software and applications installed on these devices.
* Step 3 : Generate inventory reports from FortiClient EMS to meet the audit requirements.
:
Fortinet Documentation on FortiClient EMS FortiClient EMS Administration Guide By using the FortiClient EMS connector, you can effectively inventory all software and applications on Windows devices, ensuring compliance with the security audit requirements.
NEW QUESTION # 44
Refer to the exhibit,
which shows the partial output of the MITRE ATT&CK Enterprise matrix on FortiAnalyzer.
Which two statements are true? (Choose two.)
- A. There are event handlers that cover tactic T1071.
- B. There are four subtechniques that fall under technique T1071.
- C. There are 15 events associated with the tactic.
- D. There are four techniques that fall under tactic T1071.
Answer: A,B
Explanation:
* Understanding the MITRE ATT&CK Matrix:
* The MITRE ATT&CK framework is a knowledge base of adversary tactics and techniques based on real-world observations.
* Each tactic in the matrix represents the "why" of an attack technique, while each technique represents "how" an adversary achieves a tactic.
* Analyzing the Provided Exhibit:
* The exhibit shows part of the MITRE ATT&CK Enterprise matrix as displayed on FortiAnalyzer.
* The focus is on technique T1071 (Application Layer Protocol), which has subtechniques labeled T1071.001, T1071.002, T1071.003, and T1071.004.
* Each subtechnique specifies a different type of application layer protocol used for Command and Control (C2):
* T1071.001 Web Protocols
* T1071.002 File Transfer Protocols
* T1071.003 Mail Protocols
* T1071.004 DNS
* Identifying Key Points:
* Subtechniques under T1071:There are four subtechniques listed under the primary technique T1071, confirming that statement B is true.
* Event Handlers for T1071:FortiAnalyzer includes event handlers for monitoring various tactics and techniques. The presence of event handlers for tactic T1071 suggests active monitoring and alerting for these specific subtechniques, confirming that statement C is true.
* Misconceptions Clarified:
* Statement A (four techniques under tactic T1071) is incorrect because T1071 is a single technique with four subtechniques.
* Statement D (15 events associated with the tactic) is misleading. The number 15 refers to the techniques under the Application Layer Protocol, not directly related to the number of events.
Conclusion:
* The accurate interpretation of the exhibit confirms that there are four subtechniques under technique T1071 and that there are event handlers covering tactic T1071.
References:
MITRE ATT&CK Framework documentation.
FortiAnalyzer Event Handling and MITRE ATT&CK Integration guides.
NEW QUESTION # 45
Which two statements about the FortiAnalyzer Fabric topology are true? (Choose two.)
- A. Fabric members must be in analyzer mode.
- B. Logging devices must be registered to the supervisor.
- C. The supervisor uses an API to store logs, incidents, and events locally.
- D. Downstream collectors can forward logs to Fabric members.
Answer: A,B
Explanation:
* Understanding FortiAnalyzer Fabric Topology:
* The FortiAnalyzer Fabric topology is designed to centralize logging and analysis across multiple devices in a network.
* It involves a hierarchy where the supervisor node manages and coordinates with other Fabric members.
* Analyzing the Options:
* Option A:Downstream collectors forwarding logs to Fabric members is not a typical configuration. Instead, logs are usually centralized to the supervisor.
* Option B:For effective management and log centralization, logging devices must be registered to the supervisor. This ensures proper log collection and coordination.
* Option C:The supervisor does not primarily use an API to store logs, incidents, and events locally. Logs are stored directly in the FortiAnalyzer database.
* Option D:For the Fabric topology to function correctly, all Fabric members need to be in analyzer mode. This mode allows them to collect, analyze, and forward logs appropriately within the topology.
* Conclusion:
* The correct statements regarding the FortiAnalyzer Fabric topology are that logging devices must be registered to the supervisor and that Fabric members must be in analyzer mode.
References:
Fortinet Documentation on FortiAnalyzer Fabric Topology.
Best Practices for Configuring FortiAnalyzer in a Fabric Environment.
NEW QUESTION # 46
Refer to Exhibits: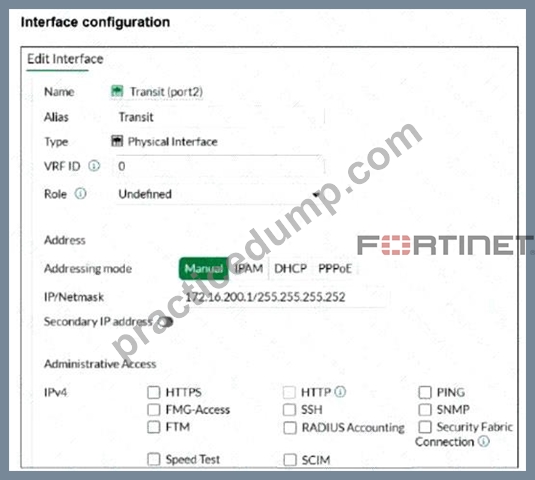
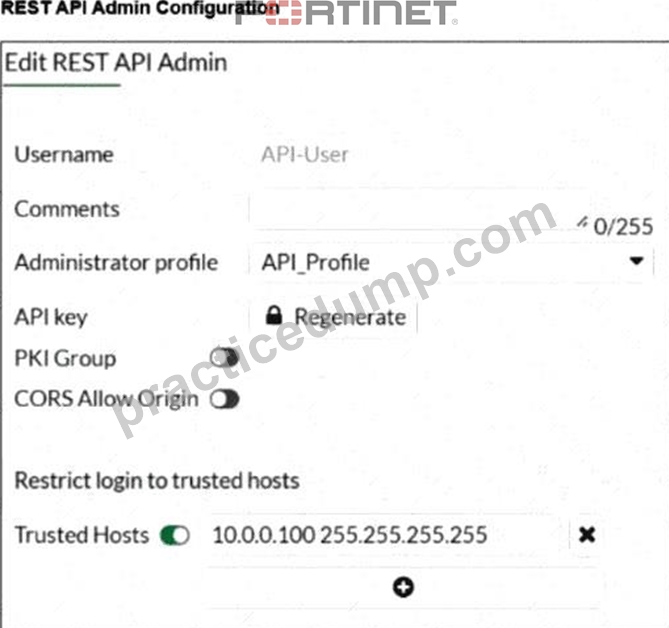
You configured the FortiGate connector on FortiSOAR. You want to allow FortiSOAR 10.200.200.160 to perform actions on FortiGate 172.16.200.1 . However, the connection attempt fails. Assume that the FortiGate connector is configured correctly on the FortiSOAR side.
Which two configurations are required on FortiGate? Choose two answers.
- A. HTTPS must be enabled on the FortiGate interface that FortiSOAR will communicate with.
- B. The FortiGate interface role must be set to Custom API Endpoint.
- C. The administrator profile must have System read and write permissions.
- D. FortiSOAR IP address must be added under Trusted Hosts.
Answer: A,D
Explanation:
Exact Extract: "You must enable HTTPS on the FortiGate interface that the FortiGate connector on FortiSOAR is pointing to. If trusted hosts are enabled on the API administrator used by FortiSOAR, you must add the FortiSOAR IP address to the list." Exact Extract: "When assigning an administrator profile to the API user, you must assign the required permissions to perform the actions you want completed on the connector. Consult the connector documentation for more information." The correct answers are A and B . In the exhibit, the FortiGate interface Transit (port2) has no administrative access enabled. Because the FortiSOAR FortiGate connector communicates with FortiGate by API over HTTPS, HTTPS must be enabled on the FortiGate interface that FortiSOAR targets. Also, the REST API admin has Trusted Hosts enabled, but the trusted host shown is 10.0.0.100 , while the FortiSOAR IP is 10.200.200.160 . FortiGate will reject API access from FortiSOAR unless 10.200.200.160/32 is allowed as a trusted host. Option C can matter for specific actions, but it is not the shown connection failure. Option D is nonsense; FortiGate interface roles do not include "Custom API Endpoint." Technical Deep Dive: The FortiSOAR connector calls the FortiGate REST API over HTTPS, so FortiGate must accept HTTPS management traffic on the target interface and must allow the API user source IP. CLI equivalent:
config system interface
edit " port2 "
set allowaccess https
next
end
config system api-user
edit " API-User "
set accprofile " API_Profile "
config trusthost
edit 1
set ipv4-trusthost 10.200.200.160 255.255.255.255
next
end
next
end
NP/CP hardware offloading is irrelevant here. This is management-plane HTTPS/API access, not data- plane traffic acceleration.
NEW QUESTION # 47
Which statement best describes the MITRE ATT&CK framework?
- A. It provides a high-level description of common adversary activities, but lacks technical details
- B. It covers tactics, techniques, and procedures, but does not provide information about mitigations.
- C. It describes attack vectors targeting network devices and servers, but not user endpoints.
- D. It contains some techniques or subtechniques that fall under more than one tactic.
Answer: D
Explanation:
* Understanding the MITRE ATT&CK Framework:
* The MITRE ATT&CK framework is a comprehensive matrix of tactics and techniques used by adversaries to achieve their objectives.
* It is widely used for understanding adversary behavior, improving defense strategies, and conducting security assessments.
* Analyzing the Options:
* Option A:The framework provides detailed technical descriptions of adversary activities, including specific techniques and subtechniques.
* Option B:The framework includes information about mitigations and detections for each technique and subtechnique, providing comprehensive guidance.
* Option C:MITRE ATT&CK covers a wide range of attack vectors, including those targeting user endpoints, network devices, and servers.
* Option D:Some techniques or subtechniques do indeed fall under multiple tactics, reflecting the complex nature of adversary activities that can serve different objectives.
* Conclusion:
* The statement that best describes the MITRE ATT&CK framework is that it contains some techniques or subtechniques that fall under more than one tactic.
References:
MITRE ATT&CK Framework Documentation.
Security Best Practices and Threat Intelligence Reports Utilizing MITRE ATT&CK.
NEW QUESTION # 48
Refer to the exhibit.
You notice that the custom event handler you configured to detect SMTP reconnaissance activities is creating a large number of events. This is overwhelming your notification system.
How can you fix this?
- A. Decrease the time range that the custom event handler covers during the attack.
- B. Increase the trigger count so that it identifies and reduces the count triggered by a particular group.
- C. Increase the log field value so that it looks for more unique field values when it creates the event.
- D. Disable the custom event handler because it is not working as expected.
Answer: B
Explanation:
* Understanding the Issue:
* The custom event handler for detecting SMTP reconnaissance activities is generating a large number of events.
* This high volume of events is overwhelming the notification system, leading to potential alert fatigue and inefficiency in incident response.
* Event Handler Configuration:
* Event handlers are configured to trigger alerts based on specific criteria.
* The frequency and volume of these alerts can be controlled by adjusting the trigger conditions.
* Possible Solutions:
* A. Increase the trigger count so that it identifies and reduces the count triggered by a particular group:
* By increasing the trigger count, you ensure that the event handler only generates alerts after a higher threshold of activity is detected.
* This reduces the number of events generated and helps prevent overwhelming the notification system.
* Selected as it effectively manages the volume of generated events.
* B. Disable the custom event handler because it is not working as expected:
* Disabling the event handler is not a practical solution as it would completely stop monitoring for SMTP reconnaissance activities.
* Not selected as it does not address the issue of fine-tuning the event generation.
* C. Decrease the time range that the custom event handler covers during the attack:
* Reducing the time range might help in some cases, but it could also lead to missing important activities if the attack spans a longer period.
* Not selected as it could lead to underreporting of significant events.
* D. Increase the log field value so that it looks for more unique field values when it creates the event:
* Adjusting the log field value might refine the event criteria, but it does not directly control the volume of alerts.
* Not selected as it is not the most effective way to manage event volume.
* Implementation Steps:
* Step 1: Access the event handler configuration in FortiAnalyzer.
* Step 2: Locate the trigger count setting within the custom event handler for SMTP reconnaissance.
* Step 3: Increase the trigger count to a higher value that balances alert sensitivity and volume.
* Step 4: Save the configuration and monitor the event generation to ensure it aligns with expected levels.
* Conclusion:
* By increasing the trigger count, you can effectively reduce the number of events generated by the custom event handler, preventing the notification system from being overwhelmed.
Fortinet Documentation on Event Handlers and Configuration FortiAnalyzer Administration Guide Best Practices for Event Management Fortinet Knowledge Base By increasing the trigger count in the custom event handler, you can manage the volume of generated events and prevent the notification system from being overwhelmed.
NEW QUESTION # 49
You are trying to create a playbook that creates a manual task showing a list of public IPv6 addresses. You were successful in extracting all IP addresses from a previous action into a variable called ip_list , which contains both private and public IPv4 and IPv6 addresses. You must now filter the results to display only public IPv6 addresses. Which two Jinja expressions can accomplish this task? (Choose two answers)
- A. {{ vars.ip_list | ipaddr( ' !private ' ) | ipv6 }}
- B. {{ vars.ip_list | ipv6addr( ' public ' ) }}
- C. {{ vars.ip_list | ipaddr( ' public ' ) | ipv6 }}
- D. {{ vars.ip_list | ipv6 | ipaddr( ' public ' ) }}
Answer: C,D
Explanation:
In FortiSOAR 7.6 , the playbook engine utilizes the powerful ipaddr family of Jinja filters (derived from the Ansible netaddr library) to manipulate network data. To isolate public IPv6 addresses from a mixed list, the order of operations in the filter chain ensures the correct data is extracted:
* Double Filtering Sequence (B): In the expression {{ vars.ip_list | ipaddr( ' public ' ) | ipv6 }}, the first filter ipaddr( ' public ' ) processes the entire list and retains only public addresses, including both IPv4 and IPv6 versions. The second filter in the pipe, | ipv6, then takes that subset of public addresses and filters them again to keep only those that conform to the IPv6 standard. The final result is a list containing only public IPv6 addresses.
* Version-First Filtering (D): In the expression {{ vars.ip_list | ipv6 | ipaddr( ' public ' ) }}, the logic is reversed but equally effective. The first filter | ipv6 immediately strips all IPv4 and non-IP strings from the list, leaving only IPv6 addresses (both private and public). The subsequent filter | ipaddr( ' public ' ) then evaluates these IPv6 addresses and discards any that fall within the private/unique-local ranges (like ULA or link-local), resulting in the same set of public IPv6 addresses.
Why other options are incorrect:
* A (ipv6addr ' public ' ): While ipv6addr is a valid filter in many Ansible environments, FortiSOAR ' s standard documentation for manual task creation and data manipulation primarily emphasizes the use of the generic ipaddr filter with specific flags or chained version filters (like | ipv6) to ensure cross- compatibility with the underlying Python libraries used by the SOAR engine.
* C (!private syntax): The ipaddr filter utilizes specific keywords for classification. While " not private " is the logical requirement, the filter expects positive assertions such as ' public ' , ' private ' , or ' multicast ' . The !private syntax is not a supported or documented operator for this filter within the Fortinet SOC ecosystem.
NEW QUESTION # 50
Refer to the exhibit.
What are the two mistakes in the incident subpattern rule configuration? Choose two answers.
- A. The aggregate operator is incorrect.
- B. The Group By attributes conflict with each other.
- C. The mandatory Event Type attribute is missing.
- D. The subpattern is missing a time window definition.
Answer: A,C
Explanation:
Exact Extract: "Rule subpatterns consist of a filter, aggregate, and group by condition. In the Filters section, you must specify the criteria for determining which event attributes and values the rule monitors... Next, in the Aggregate section, you must define the number of event matches required for the rule to trigger. Finally, in the Group By section, you must define which event attributes will be used to group the events before the group constraints are applied." Exact Extract: "FortiSIEM always sets the Aggregate condition to COUNT(Matched Events) > = 1." The two mistakes are B and D . In the exhibit, the aggregate condition is configured as COUNT(Matched Events) < 1 , which is logically wrong for an incident rule that should trigger when a matching event occurs.
It should be COUNT(Matched Events) > = 1 or another positive threshold, depending on the detection objective. The second problem is that the filter uses Windows Event Category = Win-Security-517 instead of defining the mandatory Event Type condition. FortiSIEM rules should match the normalized event type, such as Event Type = Win-Security-517 , because Event Type identifies the parsed event FortiSIEM is correlating. The Group By fields-Reporting IP, Computer, and Service Name-do not conflict; they define how matching events are grouped. The time window is normally configured at the rule condition level, not necessarily inside this subpattern edit view, so A is not the best answer.
Technical Deep Dive: FortiSIEM correlation logic works in three layers: the Filter selects candidate events, the Aggregate decides whether enough matching events exist, and Group By controls per-entity correlation. Here, using < 1 means the rule is effectively looking for zero matching events, which is not how a Windows service-event detection should be triggered. Also, Windows Event Category is not the normalized FortiSIEM event identity; Event Type is the key normalized field used for rule accuracy.
This is SIEM correlation logic only; FortiGate NP/CP offloading is irrelevant because no packet- forwarding or ASIC inspection path is involved.
NEW QUESTION # 51
A large enterprise FortiSIEM deployment is experiencing delays in log correlation and analytics.
Which architectural adjustment is most appropriate? Choose one answer.
- A. Increase supervisor CPU and memory.
- B. Add more collectors.
- C. Limit the number of rules using streaming mode.
- D. Add more workers.
Answer: D
Explanation:
Exact Extract: "Workers: Correlation, real-time, and historical search." The guide also states: "For larger environments that need greater event handling throughput, you can deploy FortiSIEM in a cluster of supervisor and worker VMs." The correct answer is B. FortiSIEM workers are responsible for correlation, real-time analytics, and historical searches. If a large enterprise deployment is experiencing delays specifically in log correlation and analytics, the correct architectural scaling action is to add more workers. Collectors help with distributed collection and discovery, but they do not solve analytics-processing bottlenecks. The Supervisor hosts the UI, CMDB, and reporting, so simply increasing supervisor resources is not the best targeted fix. A is a tuning option, not the appropriate architectural scale-out answer.
Technical Deep Dive: In large FortiSIEM designs, collectors reduce collection load and WAN complexity, while workers increase analytics throughput. If correlation latency grows, check EPS, rule volume, search workload, storage backend performance, and worker utilization. Scaling workers distributes event processing and search operations more effectively. FortiGate NP/CP offloading is unrelated because this bottleneck exists inside FortiSIEM analytics infrastructure.
NEW QUESTION # 52
Refer to the exhibit.
You notice that the custom event handler you configured to detect SMTP reconnaissance activities is creating a large number of events. This is overwhelming your notification system.
How can you fix this?
- A. Decrease the time range that the custom event handler covers during the attack.
- B. Increase the trigger count so that it identifies and reduces the count triggered by a particular group.
- C. Increase the log field value so that it looks for more unique field values when it creates the event.
- D. Disable the custom event handler because it is not working as expected.
Answer: B
Explanation:
* Understanding the Issue:
* The custom event handler for detecting SMTP reconnaissance activities is generating a large number of events.
* This high volume of events is overwhelming the notification system, leading to potential alert fatigue and inefficiency in incident response.
* Event Handler Configuration:
* Event handlers are configured to trigger alerts based on specific criteria.
* The frequency and volume of these alerts can be controlled by adjusting the trigger conditions.
* Possible Solutions:
* A. Increase the trigger count so that it identifies and reduces the count triggered by a particular group:
* By increasing the trigger count, you ensure that the event handler only generates alerts after a higher threshold of activity is detected.
* This reduces the number of events generated and helps prevent overwhelming the notification system.
* Selected as it effectively manages the volume of generated events.
* B. Disable the custom event handler because it is not working as expected:
* Disabling the event handler is not a practical solution as it would completely stop monitoring for SMTP reconnaissance activities.
* Not selected as it does not address the issue of fine-tuning the event generation.
* C. Decrease the time range that the custom event handler covers during the attack:
* Reducing the time range might help in some cases, but it could also lead to missing important activities if the attack spans a longer period.
* Not selected as it could lead to underreporting of significant events.
* D. Increase the log field value so that it looks for more unique field values when it creates the event:
* Adjusting the log field value might refine the event criteria, but it does not directly control the volume of alerts.
* Not selected as it is not the most effective way to manage event volume.
* Implementation Steps:
* Step 1: Access the event handler configuration in FortiAnalyzer.
* Step 2: Locate the trigger count setting within the custom event handler for SMTP reconnaissance.
* Step 3: Increase the trigger count to a higher value that balances alert sensitivity and volume.
* Step 4: Save the configuration and monitor the event generation to ensure it aligns with expected levels.
* Conclusion:
* By increasing the trigger count, you can effectively reduce the number of events generated by the custom event handler, preventing the notification system from being overwhelmed.
Fortinet Documentation on Event Handlers and Configuration FortiAnalyzer Administration Guide Best Practices for Event Management Fortinet Knowledge Base By increasing the trigger count in the custom event handler, you can manage the volume of generated events and prevent the notification system from being overwhelmed.
NEW QUESTION # 53
Refer to the exhibits.
The Malicious File Detect playbook is configured to create an incident when an event handler generates a malicious file detection event.
Why did the Malicious File Detect playbook execution fail?
- A. The Attach Data To Incident task failed, which stopped the playbook execution.
- B. The Attach_Data_To_lncident incident task wasexpecting an integer, but received an incorrect data format.
- C. The Get Events task did not retrieve any event data.
- D. The Create Incident task was expecting a name or number as input, but received an incorrect data format
Answer: D
Explanation:
* Understanding the Playbook Configuration:
* The "Malicious File Detect" playbook is designed to create an incident when a malicious file detection event is triggered.
* The playbook includes tasks such as Attach_Data_To_Incident, Create Incident, and Get Events.
* Analyzing the Playbook Execution:
* The exhibit shows that the Create Incident task has failed, and the Attach_Data_To_Incident task has also failed.
* The Get Events task succeeded, indicating that it was able to retrieve event data.
* Reviewing Raw Logs:
* The raw logs indicate an error related to parsing input in the incident_operator.py file.
* The error traceback suggests that the task was expecting a specific input format (likely a name or number) but received an incorrect data format.
* Identifying the Source of the Failure:
* The Create Incident task failure is the root cause since it did not proceed correctly due to incorrect input format.
* The Attach_Data_To_Incident task subsequently failed because it depends on the successful creation of an incident.
* Conclusion:
* The primary reason for the playbook execution failure is that the Create Incident task received an incorrect data format, which was not a name or number as expected.
References:
Fortinet Documentation on Playbook and Task Configuration.
Error handling and debugging practices in playbook execution.
NEW QUESTION # 54
Refer to the exhibit.
You want to configure a FortiSIEM rule that triggers when a FortiMail device reports at least 100 recipient verification failures for different email accounts in the domain acmecorp.net . What would you add or modify to accomplish this task? Choose one answer.
- A. Add a filter for Mail Receiver > = 100 .
- B. Change the status attribute filter from Status CONTAIN FAIL to Status CUSTOM EXPRESSION FAIL > = 100 .
- C. Add a filter for Mail Receiver CONTAIN acmecorp.net .
- D. Change the aggregate to COUNT(Distinct Mail Receiver) > = 100 .
Answer: D
Explanation:
Exact Extract: "The subpattern... consists of three components: Filter... Aggregate... Group By... Aggregate:
The aggregate function stipulates that five or more events within the 600-second time window must be matched. Group By: If multiple VPN login failure events have the same source IP address, reporting device, reporting IP address, and user, they are grouped together in one row, and the count column tracks the number of events for each row." Exact Extract: "FortiSIEM uses the analytics search filter conditions to create the rule subpattern Filter conditions and the search display conditions to create the rule Group by conditions. When creating rules from analytics searches, FortiSIEM always sets the Aggregate condition to COUNT(Matched Events) > = 1." The correct answer is A because the requirement is not simply "100 failed events"; it is 100 failures for different email accounts . The existing aggregate COUNT(Matched Events) > = 100 only counts total matching FortiMail rejection events. That could trigger even if one recipient address failed 100 times. To detect failures across different recipients , the aggregate must count unique recipient values, so COUNT (Distinct Mail Receiver) > = 100 is the correct modification. Option B is invalid because Mail Receiver is a field containing an email recipient value, not a numeric counter. Option C incorrectly tries to push counting logic into the Status filter; Status should remain a filter such as CONTAIN FAIL . Option D may be useful only if the domain is not already filtered, but the exhibit already includes the domain condition for acmecorp.
net , and it still would not solve the "different email accounts" requirement.
Technical Deep Dive: FortiSIEM correlation rules separate filtering from aggregation. Filters define which events qualify; aggregate functions define when the pattern becomes significant. Here, FortiMail supplies rejection events with fields such as event type, classifier, status, domain, and mail receiver. The right logic is: filter FortiMail recipient-verification failures for acmecorp.net, then aggregate on distinct Mail Receiver values. FortiGate NP/CP offloading is irrelevant here; this is SIEM-side event correlation, not packet forwarding or ASIC-accelerated inspection.
NEW QUESTION # 55
What are three capabilities of the built-in FortiSOAR Jinja editor? (Choose three answers)
- A. It creates new records in bulk.
- B. It renders output by combining Jinja expressions and JSON input.
- C. It defines conditions to trigger a playbook step.
- D. It checks the validity of a Jinja expression.
- E. It loads the environment JSON of a recently executed playbook.
Answer: B,D,E
Explanation:
Comprehensive and Detailed Explanation From FortiSOAR 7.6., FortiSIEM 7.3 Exact Extract study guide:
The built-in Jinja editor inFortiSOAR 7.6is a powerful utility designed to help playbook developers write and test complex data manipulation logic without having to execute the entire playbook. Its primary capabilities include:
* Renders output (A):The editor provides a "Preview" or "Evaluation" pane. By combining aJinja expressionwith a sampleJSON input(manually entered or loaded), the editor dynamically calculates and displays the resulting output. This allows for immediate verification of data transformation logic.
* Checks validity (B):The editor includes built-in linting and syntax validation. It alerts the developer to errors such as unclosed brackets, incorrect filter usage, or invalid syntax, ensuring that only valid Jinja code is saved into the playbook step.
* Loads environment JSON (D):One of the most significant features for troubleshooting is the ability toload the environment JSONfrom a recent execution. This populates the editor's variable context (vars) with the actual data from a specific playbook run, allowing the developer to test expressions against real-world data that recently passed through the system.
Why other options are incorrect:
* Creates new records in bulk (C):While Jinja expressions are used to format the data that goes into a record, the actual creation of records is handled by the"Create Record"step or specificConnectors, not by the Jinja editor utility itself.
* Defines conditions to trigger a playbook step (E):Jinja is thelanguageused to write conditions within a
"Decision" step or "Step Utilities," but the Jinja Editor is a tool forevaluating and testingthose expressions. The definition of the condition logic and the triggering behavior is a function of the Playbook Engine and Step configuration, not the editor's standalone capabilities.
NEW QUESTION # 56
Refer to the exhibits.
You have a playbook that, depending on whether an analyst deems the alert to be a true positive, could reference a child playbook. You need to pass variables from the parent playbook to the child playbook.
Place the steps needed to accomplish this in the correct order.
Answer:
Explanation:
Explanation:
1. Create a parameter in the child playbook.
2. Apply the parameter to the Disable User Account connector action.
3. Map data to the parameter in the Reference a playbook step in the parent playbook.
Comprehensive and Detailed Explanation From FortiSOAR 7.6., FortiSIEM 7.3 Exact Extract study guide:
InFortiSOAR 7.6, the methodology for passing data between playbooks-specifically from a parent to a
"Referenced" (child) playbook-follows a strict data flow hierarchy:
* Step 1: Create a parameter in the child playbook.Before a parent can send data, the child playbook must be configured to receive it. This is done by adding "Input Parameters" in theStartstep of the child playbook (configured as a "Referenced" trigger). These parameters act as the "inbox" for external data.
* Step 2: Apply the parameter to the connector action.Once the child playbook has the parameter defined (e.g., user_id), you must use a Jinja expression like {{vars.input.params.user_id}} within the child's action steps (such as theActive Directory: Disable User Accountconnector) so that the child playbook actually utilizes the data it receives.
* Step 3: Map data to the parameter in the parent playbook.Finally, in the parent playbook, when you add theReference a Playbookstep and select the child playbook, FortiSOAR automatically displays the parameters created in Step 1. You then map existing variables from the parent's environment (e.g., from a previous "Search by SamAccountName" step) into these fields to complete the hand-off.
Why other options are excluded:
* Create a manual trigger and assign the user to a new variable:While manual triggers capture data, they are not the mechanism forpassingdata between nested playbooks; they are for user-to-system interaction.
* Create a parameter in the parent playbook:Parameters in a parent playbook are used to receive data fromoutside(like an external API or manual input), not to send datadownto a child. The child defines what it needs; the parent simply provides it in the Reference step.
NEW QUESTION # 57
You are trying to create a playbook that creates a manual task showing a list of public IPv6 addresses. You were successful in extracting all IP addresses from a previous action into a variable calledip_list, which contains both private and public IPv4 and IPv6 addresses. You must now filter the results to display only public IPv6 addresses. Which two Jinja expressions can accomplish this task? (Choose two answers)
- A. {{ vars.ip_list | ipaddr('public') | ipv6 }}
- B. {{ vars.ip_list | ipv6 | ipaddr('public') }}
- C. {{ vars.ip_list | ipaddr('!private') | ipv6 }}
- D. {{ vars.ip_list | ipv6addr('public') }}
Answer: A,B
Explanation:
Comprehensive and Detailed Explanation From FortiSOAR 7.6., FortiSIEM 7.3 Exact Extract study guide:
InFortiSOAR 7.6, the playbook engine utilizes the powerful ipaddr family of Jinja filters (derived from the Ansible netaddr library) to manipulate network data. To isolate public IPv6 addresses from a mixed list, the order of operations in the filter chain ensures the correct data is extracted:
* Double Filtering Sequence (B):In the expression {{ vars.ip_list | ipaddr('public') | ipv6 }}, the first filter ipaddr('public') processes the entire list and retains only public addresses, including both IPv4 and IPv6 versions. The second filter in the pipe, | ipv6, then takes that subset of public addresses and filters them again to keep only those that conform to the IPv6 standard. The final result is a list containing only public IPv6 addresses.
* Version-First Filtering (D):In the expression {{ vars.ip_list | ipv6 | ipaddr('public') }}, the logic is reversed but equally effective. The first filter | ipv6 immediately strips all IPv4 and non-IP strings from the list, leaving only IPv6 addresses (both private and public). The subsequent filter | ipaddr('public') then evaluates these IPv6 addresses and discards any that fall within the private/unique-local ranges (like ULA or link-local), resulting in the same set of public IPv6 addresses.
Why other options are incorrect:
* A (ipv6addr 'public'):While ipv6addr is a valid filter in many Ansible environments, FortiSOAR's standard documentation for manual task creation and data manipulation primarily emphasizes the use of the generic ipaddr filter with specific flags or chained version filters (like | ipv6) to ensure cross- compatibility with the underlying Python libraries used by the SOAR engine.
* C (!private syntax):The ipaddr filter utilizes specific keywords for classification. While "not private" is the logical requirement, the filter expects positive assertions such as 'public', 'private', or 'multicast'. The
!private syntax is not a supported or documented operator for this filter within the Fortinet SOC ecosystem.
NEW QUESTION # 58
Match the FortiSIEM device type to its description. Select each FortiSIEM device type in the left column, hold and drag it to the blank space next to its corresponding description in the column on the right.
Answer:
Explanation:
* Collector 2. Worker 3. Supervisor 4. Agent
* The FortiSIEM 7.3 architecture is built upon a distributed multi-tenant model consisting of several distinct functional roles to ensure scalability and performance:
* Supervisor: This is the primary management node in a FortiSIEM cluster. It hosts the Graphical User Interface (GUI), the Configuration Management Database (CMDB), and manages the overall system configurations, reporting, and dashboarding.
* Worker: These nodes are responsible for the heavy lifting of data processing. They execute real- time event correlation against the rules engine, perform historical search queries, and handle the analytics workload to ensure the Supervisor node is not overwhelmed.
* Collector: Collectors are typically deployed at remote sites or different network segments to offload log collection from the central cluster. They receive logs via Syslog, SNMP, or WMI, compress the data, and securely forward it to the Workers or Supervisor. They also perform performance monitoring of local devices.
* Agent: These are lightweight software components installed directly on endpoints (Windows
/Linux). Their primary role is to collect local endpoint logs, monitor file integrity (system changes), and track user activity that cannot be captured via traditional network-based logging.
NEW QUESTION # 59
Refer to the exhibits.
You configured a custom event handler and an associated rule to generate events whenever FortiMail detects spam emails. However, you notice that the event handler is generating events for both spam emails and clean emails.
Which change must you make in the rule so that it detects only spam emails?
- A. In the Trigger an event when field, select Within a group, the log field Spam Name (snane) has 2 or more unique values.
- B. In the Log Type field, select Anti-Spam Log (spam)
- C. Disable the rule to use the filter in the data selector to create the event.
- D. In the Log filter by Text field, type type==spam.
Answer: B
Explanation:
* Understanding the Custom Event Handler Configuration:
* The event handler is set up to generate events based on specific log data.
* The goal is to generate events specifically for spam emails detected by FortiMail.
* Analyzing the Issue:
* The event handler is currently generating events for both spam emails and clean emails.
* This indicates that the rule's filtering criteria are not correctly distinguishing between spam and non-spam emails.
* Evaluating the Options:
* Option A:Selecting the "Anti-Spam Log (spam)" in the Log Type field will ensure that only logs related to spam emails are considered. This is the most straightforward and accurate way to filter for spam emails.
* Option B:Typing type==spam in the Log filter by Text field might help filter the logs, but it is not as direct and reliable as selecting the correct log type.
* Option C:Disabling the rule to use the filter in the data selector to create the event does not address the issue of filtering for spam logs specifically.
* Option D:Selecting "Within a group, the log field Spam Name (snane) has 2 or more unique values" is not directly relevant to filtering spam logs and could lead to incorrect filtering criteria.
* Conclusion:
* The correct change to make in the rule is to select "Anti-Spam Log (spam)" in the Log Type field. This ensures that the event handler only generates events for spam emails.
References:
Fortinet Documentation on Event Handlers and Log Types.
Best Practices for Configuring FortiMail Anti-Spam Settings.
NEW QUESTION # 60
Refer to the exhibit.
How do you add a piece of evidence to the Action Logs Marked As Evidence area? (Choose one answer)
- A. By executing a playbook with the Save Execution Logs option enabled
- B. By linking an indicator to the war room
- C. By creating an evidence collection task and attaching a file
- D. By tagging output or a workspace comment with the keyword Evidence
Answer: D
Explanation:
In FortiSOAR 7.6 , the War Room is a collaborative space designed for high-priority incident investigation.
The Evidences tab within the Investigate view (as shown in the exhibit) is specifically designed to highlight critical findings found during the investigation process.
* Evidence Tagging: To populate the Action Logs Marked As Evidence section, an analyst must specifically tag a relevant log entry, a playbook output, or a comment within the collaboration workspace with the system-defined keyword " Evidence " .
* Automatic Categorization: Once the tag is applied, FortiSOAR automatically parses these entries and displays them in this centralized view. This allows team members and stakeholders to quickly view substantiated facts and proof gathered during the " Root Cause Analysis " phase without sifting through all raw action logs.
* Manual vs. Action Logs: The exhibit shows two distinct areas: " Manually Upload Evidences " (where files like the CSLAB document shown can be dragged and dropped) and " Action Logs Marked As Evidence. " The latter is reserved exclusively for system-generated logs or comments that have been promoted to evidence status via tagging.
Why other options are incorrect:
* By linking an indicator to the war room (B): Linking indicators associates technical artifacts (like IPs or hashes) with the record, but it does not automatically classify them as evidence within the War Room action log view.
* By creating an evidence collection task and attaching a file (C): While this is a valid step in an investigation, attaching a file to a task typically places it in the " Attachments " or " Manually Upload Evidences " area, rather than the " Action Logs " section specifically.
* By executing a playbook with the Save Execution Logs option enabled (D): Saving execution logs ensures a trail of what the playbook did, but it does not mark the output as " Evidence " unless the specific logic or a manual analyst action applies the " Evidence " tag to the resulting log entry.
NEW QUESTION # 61
Refer to the exhibits.
The Malicious File Detect playbook is configured to create an incident when an event handler generates a malicious file detection event.
Why did the Malicious File Detect playbook execution fail?
- A. The Attach Data To Incident task failed, which stopped the playbook execution.
- B. The Attach_Data_To_lncident incident task wasexpecting an integer, but received an incorrect data format.
- C. The Get Events task did not retrieve any event data.
- D. The Create Incident task was expecting a name or number as input, but received an incorrect data format
Answer: D
Explanation:
* Understanding the Playbook Configuration:
* The "Malicious File Detect" playbook is designed to create an incident when a malicious file detection event is triggered.
* The playbook includes tasks such as Attach_Data_To_Incident, Create Incident, and Get Events.
* Analyzing the Playbook Execution:
* The exhibit shows that the Create Incident task has failed, and the Attach_Data_To_Incident task has also failed.
* The Get Events task succeeded, indicating that it was able to retrieve event data.
* Reviewing Raw Logs:
* The raw logs indicate an error related to parsing input in the incident_operator.py file.
* The error traceback suggests that the task was expecting a specific input format (likely a name or number) but received an incorrect data format.
* Identifying the Source of the Failure:
* The Create Incident task failure is the root cause since it did not proceed correctly due to incorrect input format.
* The Attach_Data_To_Incident task subsequently failed because it depends on the successful creation of an incident.
* Conclusion:
* The primary reason for the playbook execution failure is that the Create Incident task received an incorrect data format, which was not a name or number as expected.
References:
Fortinet Documentation on Playbook and Task Configuration.
Error handling and debugging practices in playbook execution.
NEW QUESTION # 62
......
Provide Valid Dumps To Help You Prepare For Fortinet NSE 7 - Security Operations 7.6 Architect Exam: https://www.practicedump.com/NSE7_SOC_AR-7.6_actualtests.html
NSE7_SOC_AR-7.6 Dumps Questions [2026] Pass for Exam: https://drive.google.com/open?id=16r20--wOAKHzLOYO8pjmGBWDohvzG9WA